George Santos Pleads Not Guilty To 13 Federal Charges

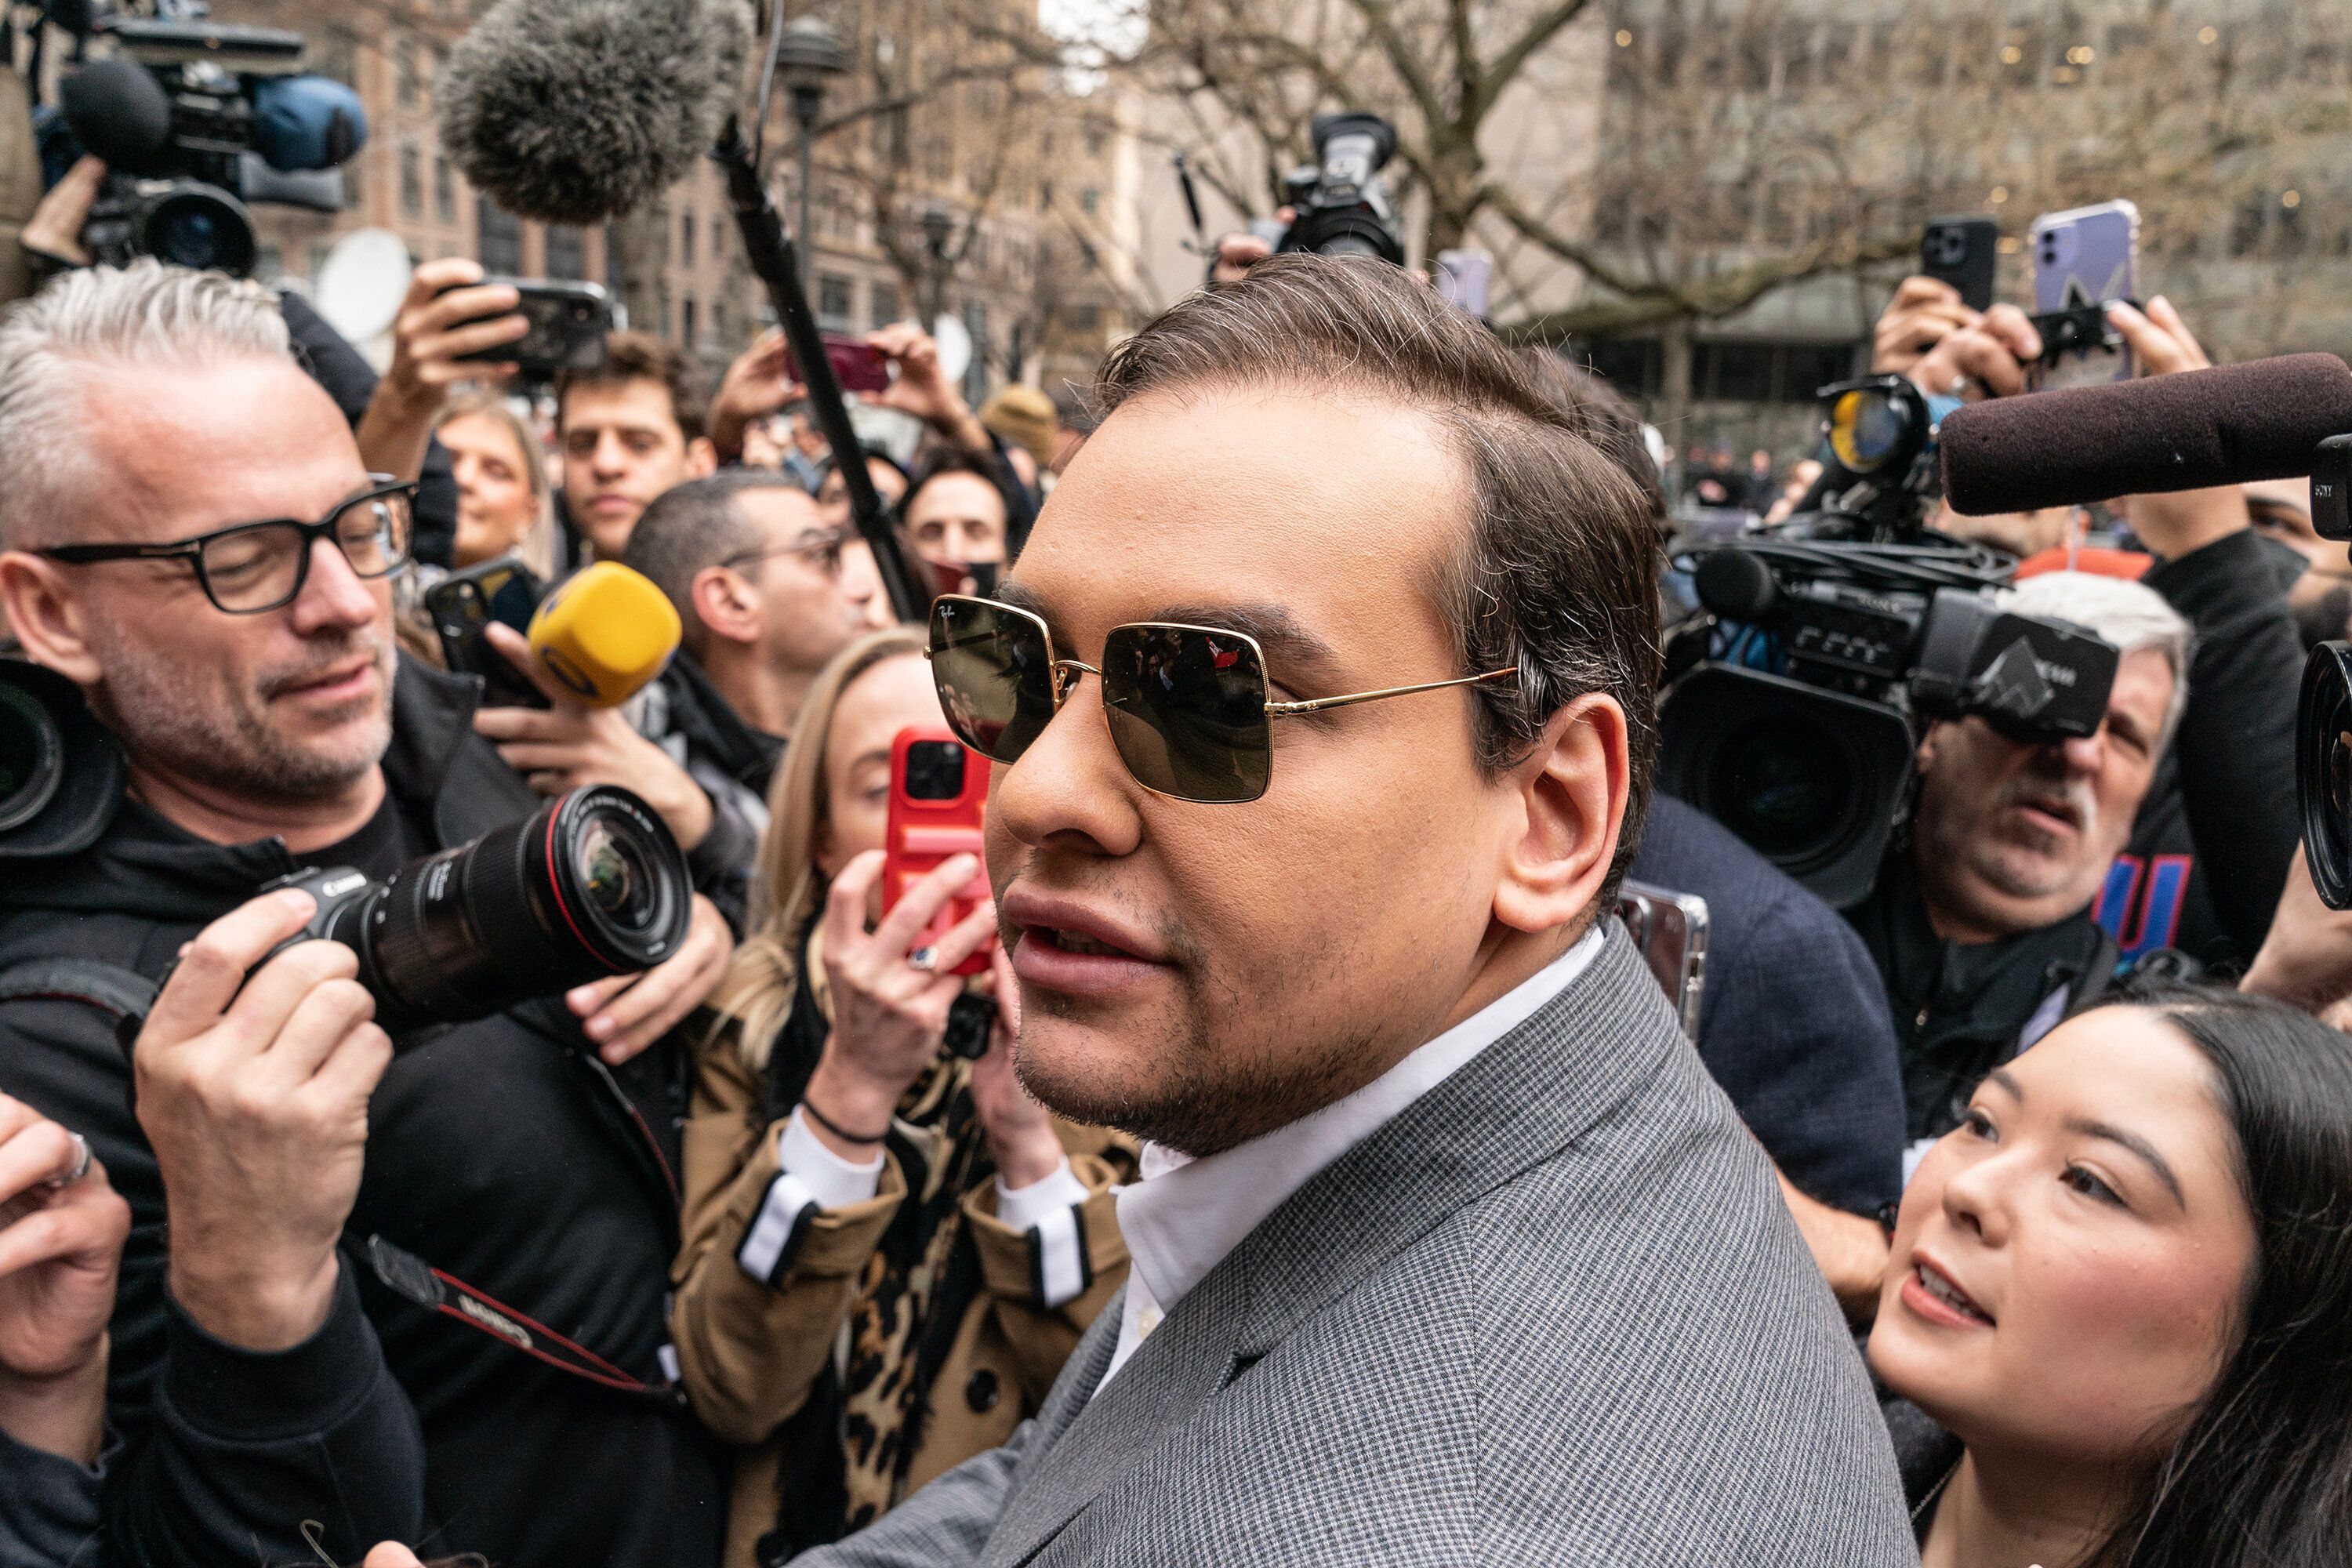
George Santos, the New York Republican who became the subject of ridicule for the extent to which he lied about his background, appeared in federal court Wednesday to be arraigned on 13 counts after turning himself into authorities earlier in the day.

He pleaded not guilty, multiple outlets reported.

Santos, 34, was elected in November to represent portions of Long Island and Queens, but in the weeks and months afterward, a number of reports showed he was not exactly the wealthy young businessman he claimed to be. While he admitted in December certain details — that he attended two top colleges and worked at prestigious Wall Street firms — were false, he denied and even defended others while refusing calls to resign.

Santos entered the Long Island courtroom with a scowl, a New York Times reporter observed.

His lawyer, Joseph Murray, said that Santos plans to continue campaigning for reelection and asked that he be free to travel to do so, according to The Associated Press. He surrendered his passport and was released on a $500,000 bond.

Outside the courthouse, Santos asserted that he had “plenty of evidence” that would supposedly clear his name.

“The reality is, it’s a witch hunt,” Santos told a crowd of reporters angling for a comment. “Because it makes no sense that [after] four months, five months — I’m indicted.”

“I will not resign,” he said.

The charges against Santos span both his personal and public life.

Federal prosecutors allege that Santos pocketed $25,000 in donations to his campaign beginning in 2022, spending the money on luxury clothes, car payments and his credit cards instead of legitimate things like political ads. In 2020, Santos allegedly received pandemic-related unemployment benefits totaling more than $24,000 from the state of New York while earning a $120,000 salary from a company in Florida.

Prosecutors also say he lied when filling out financial disclosure forms needed to run for Congress ― both in his unsuccessful 2020 campaign and his successful 2022 campaign. Santos allegedly overstated his income and assets in the 2022 filing to the tune of millions.

The case against him is a product of the Justice Department’s Public Integrity Section and local agencies.

Authorities at the federal and local level promised to investigate Santos late last year amid public outcry over the new congressman’s apparent penchant for spinning yarns.

The list of Santos’ claims has become unwieldily and, in many instances, bizarre. He has said that he is Jewish (later amended to “Jew-ish”), that his mother was in the twin towers on 9/11, that several of his employees died in the mass shooting at Orlando’s Pulse nightclub, and that he survived a brain tumor — among many other tales.

A former roommate, Gustavo Ribeiro Trelha, alleged in a sworn statement earlier this year that Santos was the ringleader of a credit card scheme in 2017 that led to Trelha serving jail time before being deported back to Brazil. (Santos denies the accusation.) The scheme is not mentioned in the federal indictment, but Politico reported in March that the case remains open.

In yet another instance of alleged fraud, Santos reportedly agreed to a deal with Brazilian prosecutors who say he wrote fraudulent checks in 2008. Part of the deal included a formal admission that Santos did the crime and would pay damages to the elderly man whose checkbook was taken, according to CNN.

In the US, however, Santos has denied that he is lawbreaker.

“I am not a criminal here — not here or in Brazil or any jurisdiction in the world. Absolutely not. That didn’t happen,” he told The New York Post in December.

Share Button

Dark clouds on the horizon

Our industrialized society releases many and various pollutants into the world. Combustion in particular produces aerosol mass including black carbon. Although this only accounts for a few percent of aerosol particles, black carbon is especially problematic due to its ability to absorb heat and impede the heat reflection capabilities of surfaces such as snow. So, it’s essential to know how black carbon interacts with sunlight. Researchers have quantified the refractive index of black carbon to the most accurate degree yet which might impact climate models.

There are many factors driving climate change; some are very familiar, such as carbon dioxide emissions from burning fossil fuels, sulfur dioxide from cement manufacture or methane emissions from animal agriculture. Black carbon aerosol particles, also from combustion, are less covered in the news but are particularly important. Essentially soot, black carbon is very good at absorbing heat from sunlight and storing it, adding to atmospheric heat. At the same time, given dark colors are less effective at reflecting light and therefore heat, as black carbon covers lighter surfaces including snow, it reduces the potential of those surfaces to reflect heat back into space.

“Understanding the interaction between black carbon and sunlight is of fundamental importance in climate research,” said Assistant Professor Nobuhiro Moteki from the Department of Earth and Planetary Science at the University of Tokyo. “The most critical property of black carbon in this regard is its refractive index, basically how it redirects and disperses incoming light rays. However, existing measurements of black carbon’s refractive index were inaccurate. My team and I undertook detailed experiments to improve this. With our improved measurements, we now estimate that current climate models may be underestimating the absorption of solar radiation due to black carbon by a significant 16%.”

Previous measurements of the optical properties of black carbon were often confounded by factors such as lack of pure samples, or difficulties in measuring light interactions with particles of differing complex shapes. Moteki and his team improved this situation by capturing the black carbon particles in water, then isolating them with sulfates or other water-soluble chemicals. By isolating the particles, the team was better able to shine light on them and analyze the way they scatter, which gave researchers the data to calculate the value of refractive index.

“We measured the amplitude, or strength, and phase, or step, of the light scattered from black carbon samples isolated in water,” said Moteki. “This allowed us to calculate what is known as the complex refractive index of black carbon. Complex because rather than being a single number, it’s a value that contains two parts, one of which is ‘imaginary’ (concerned with absorption), though its impact is very, very real. Such complex numbers with imaginary components are actually very common in the field of optical science and beyond.”

As the new optical measurements of black carbon imply that current climate models are underestimating its contribution to atmospheric warming, the team hopes that other climate researchers and policymakers can make use of their findings. The method developed by the team to ascertain the complex refractive index of particles can be applied to materials other than black carbon. This allows for the optical identification of unknown particles in the atmosphere, ocean or ice cores, and the evaluation of optical properties of powdered materials, not just those related to the ongoing problem of climate change.

Share Button

Giants of the Jurassic seas were twice the size of a killer whale

Over 20 years ago, the BBC’s Walking with Dinosaurs TV documentary series showed a 25-metre long Liopleurodon. This sparked heated debates over the size of this pliosaur as it was thought to have been wildly overestimated and more likely to have only reached an adult size of just over six metres long.

The speculation was set to continue, but now a chance discovery in an Oxfordshire museum has led to University of Portsmouth palaeontologists publishing a paper on a similar species potentially reaching a whopping 14.4 metres — twice the size of a killer whale.

Professor David Martill from the University of Portsmouth’s School of the Environment, Geography and Geosciences, said: “I was a consultant for the BBC’s pilot programme ‘Cruel Sea’ and I hold my hands up — I got the size of Liopleurodon horrendously wrong. I based my calculations on some fragmentary material which suggested a Liopleurodon could grow to a length of 25 metres, but the evidence was scant and it caused a lot of controversy at the time.

“The size estimate on the BBC back in 1999 was overdone, but now we have some evidence that is much more reliable after a serendipitous discovery of four enormous vertebrate.”

Professor Martill’s co-author, Megan Jacobs, was photographing an ichthyosaur skeleton at Abingdon County Hall Museum, while Dave looked through drawers of fossils. He found a large vertebra and was thrilled to discover the curator had three more of them in storage.

The vertebrae are clearly identifiable as being closely related to a Pliosaurus species or similar animal. Pliosaurs were like plesiosaurs, but with a bigger elongated head, similar to a crocodile, and a shorter neck. They had four flippers, which acted as powerful paddles to propel them through water and a relatively short tail.

After conducting topographic scans, Professor Martill and colleagues calculated this Late Jurassic marine reptile could have grown to between 9.8 and 14.4 metres long.

He said: “We know these pliosaurs were very fearsome animals swimming in the seas that covered Oxfordshire 145-152 million years ago. They had a massive skull with huge protruding teeth like daggers — as big, if not bigger than a T. rex, and certainly more powerful.

“They were at the top of the marine food chain and probably preyed on ichthyosaurs, long-necked plesiosaurs and maybe even smaller marine crocodiles, simply by biting them in half and taking chunks off them. We know they were massacring smaller marine reptiles because you can see bite marks in ichthyosaur bones in examples on display in The Etches Collection in Dorset.”

The vertebrae were originally discovered during temporary excavations at Warren Farm in the River Thames Valley in Oxfordshire and come from the Kimmeridge Clay Formation. This deposit is Late Jurassic in age, around 152 million years old.

Professor Martill added: “It’s wonderful to prove there was indeed a truly gigantic pliosaur species in the Late Jurassic seas. Although not yet on a par with the claims made for Liopleurodon in the iconic BBC TV series Walking With Dinosaurs, it wouldn’t surprise me if one day we find some clear evidence that this monstrous species was even bigger.”

Share Button

Human pangenome reference will enable more complete and equitable understanding of genomic diversity

UC Santa Cruz scientists, along with a consortium of researchers, have released a draft of the first human pangenome — a new, usable reference for genomics that combines the genetic material of 47 individuals from different ancestral backgrounds to allow for a deeper, more accurate understanding of worldwide genomic diversity.

By adding 119 million bases — the “letters” in DNA sequences — to the existing genomics reference, the pangenome provides a representation of human genetic diversity that was not possible with a single reference genome. It is highly accurate, more complete and dramatically increases the detection of variants in the human genome, as shown in a collection of groundbreaking papers published today in the journals Nature, Genome Research, Nature Biotechnology, and Nature Methods.

The pangenome was produced by the Human Pangenome Reference Consortium (HPRC), which is co-led by UCSC’s Associate Professor of Biomolecular Engineering Benedict Paten and Assistant Professor of Biomolecular Engineering Karen Miga and is now available for use in an assembly hub on the UCSC Genome Browser. More than a dozen UCSC researchers and students are contributors to this project, which will continue into 2024 when the researchers plan to release a final pangenome with genomic information from 350 individuals.

“We are introducing more diversity and equity into the reference by sampling diverse human beings and including them in this structure that everyone can use,” said Paten, who is the senior author on the main marker paper. “One genome isn’t enough to represent everybody — the pangenome will ultimately be something that is inclusive and representative.”

Understanding genomic variation

Each person’s genome varies slightly — by about 0.4 percent compared to the next person, on average — and understanding these differences can provide insight into their health, help to diagnose disease, predict medical outcomes, and guide treatments. Using the pangenome reference will improve scientists’ ability to detect and understand variation in future studies.

Typically when scientists and clinicians study an individual’s genome to look for variation, they compare that individuals’ DNA to that of a standard reference to determine where there are differences of one or more base pairs. Until now, the reference genome has primarily been represented by a single sequence for each human chromosome, mostly sourced from one individual. But, this reference is nearly 20 years old and fundamentally limited in that it can not represent the wealth of genetic variations present in the human population. This introduces an issue called reference bias into genome analysis.

In contrast, the new pangenome is a reference that combines the genomes of 47 individuals from various ancestral backgrounds. The pangenome looks like a linear reference in areas where the sequences have the same bases, and expands to show the areas where there are differences. It represents many different versions of the human genome sequence at the same time, and gives scientists a more accurate point of comparison for variation that is present in some populations but not others.

“One genome can’t possibly represent all of the rich variation we know can be observed and studied around the world,” said Miga, Director of the HPRC Production Center at UCSC. “The No. 1 goal of the human pangenome reference is to try to broaden the representation of a reference resource to be more inclusive and more equitable for studying the human species, as a collection of references and not just one.”

Genomic variation can be small, consisting of differences of just one or a few DNA bases, or it can be large structural variants, classified as variants that are 50 base pairs or larger. These larger, structural variants can have important health implications. Until now, researchers have been unable to identify more than 70 percent of the structural variants that exist in human genomes due to limited technologies and the bias of using a single reference sequence.

Of the 119 million new bases added to the reference with the pangenome, roughly 90 million of these derive from structural variation. Structural variants are complex and may be inversions of sequences, insertions, deletions, or tandem repeats — a segment of two or more bases repeated numerous times. These new bases will help researchers to study regions in the genome for which there was previously no reference, and potentially be able to associate structural variants with disease in future studies.

“Now, we can map to more structural variants, so we’re finding features and areas in the genome that just weren’t there before,” Miga said. “That’s exciting because it’s allowing us to look at gene regulation in a unique way that we couldn’t study before, because those areas probably would have been inappropriately mapped or just ignored altogether.”

Using the pangenome reference for genomic analysis increases the detection of structural variants by 104 percent as compared to detection using the standard reference. The pangenome reference also increases the accuracy of calling small variants, those just a few bases long, by about 34 percent because of the increased amount of data present in the pangenome.

Each human carries a paired set of chromosomes — one set inherited from the mother and one from the father. The individual genomes present in the pangenome reference contains haplotype-resolved information, meaning it can confidently distinguish the two parental sets of chromosomes — a major scientific feat. Having this information will help scientists better understand how various genes and diseases are inherited.

This also means the current reference actually includes 94 distinct genome sequences, with the goal of getting to 700 by 2024.

Creating the pangenome

The pangenome was made possible through the development of advanced computational techniques to align the multiple genome sequences into one, usable reference in a structure called a pangenome graph. Paten and researchers in the UCSC Computational Genomics lab helped lead the HPRC efforts to develop the algorithmic methods needed to create this pangenome graph structure.

Because of the methods used in this project, all of the genomes within the pangenome reference are of extremely high quality and accuracy, covering more than 99 percent of each human genome with more than 99 percent accuracy.

“In the linear reference, we had only one sequence, one representation of each gene,” said Mobin Asri, a bioinformatics Ph.D. candidate at UCSC and co-first author on the main paper. “But we know that our genes have different variations in the human population. Using the pangenome graph, we want to have all of those variations in a single structure — and a graph is a natural way to do this.”

The HPRC project relies heavily on long- and ultra long-read sequencing technology to read DNA from biological samples. With recent advances, these techniques can now decode thousands to millions of base pairs of the genome at once. The long stretches of DNA reads are then assembled via specialized algorithms into more complete genomic sequences. Ideally each assembled sequence should represent the sequence of one chromosome.

Long reads contain errors about one percent of the time and current assembly algorithms are not perfect, which can cause the assembled sequences to be erroneous in some locations. To check for and correct these errors, the individual genomes that have been sequenced and assembled move through multiple tools, including a reliability pipeline developed by Asri. Once having been processed by these tools, the researchers can ensure the assemblies are accurate and complete.

After moving through Asri’s pipeline, the various genomes are compiled via complex algorithmic methods into the pangenome graph structure. Visually, the graph genome allows researchers to view differences in the various reference sequences as diverging areas in otherwise shared paths.

Building an accessible resource

All of the first 47 diploid genomes in the draft pangenome were sourced from individuals who participated in the 1000 Genomes Project (1000G), an influential effort which created a catalog of common human genetic variation from openly consented samples and was completed in 2015. The open consent status of these samples allow any researcher to access the resource without the privacy barriers that typically accompany genome research, with the aim of making the pangenome accessible to as many people as possible.

“Becoming a common resource is something that’s fundamental to the success of a human pangenome reference,” Miga said. “It has to have the ability to be accessible and open around the world to all researchers so we can use it as the foundation.”

The HPRC team is focused on outreach to ensure that the pangenome is a useful resource that will be utilized in clinics around the world. This means facilitating annotations, feedback, and input from the researchers carrying out studies using the pangenome reference.

“The draft pangenome is an important proof of principle that we hope is going to influence a lot of people and get them thinking about the pangenome and how it might affect their work,” Paten said. “Looking ahead, we see a lot of engagement with other groups — it takes a lot of different people to build something that is going to become a big community resource.”

Along with a focus on accessibility, the HPRC project has a dedicated ethics team focused on the social and legal implications of this project. They are working to anticipate challenging issues and help guide informed consent, prioritize the study of different samples, explore possible regulatory issues pertaining to clinical adoption, and work with international and Indigenous communities to incorporate their genome sequences in these broader efforts.

Continuing the legacy and future work

The human pangenome is a continuation of decades-long efforts from scientists at UC Santa Cruz to understand the biological code that underlies human life.

In 2000, Jim Kent, then a UCSC graduate student and now a research scientist at the Genomics Institute and director of the UCSC Genome Browser, wrote the code that assembled the first working draft of the human genome. UCSC scientists published it with open access to anyone who wanted to use it. Since then, UCSC has been at the forefront of genomics research.

In April 2022, UCSC’s Karen Miga co-led the Telomere-to-Telomere consortium to assemble the first complete sequencing of a human genome, filling in missing, complex regions of reference that had long eluded scientists.

“Since 2000, we’ve had a series of increasingly more accurate representations of one genome,” said David Haussler, Scientific Director of the UCSC Genomics Institute who led the UCSC team on the original Human Genome Project and advises on the pangenome project. “But no matter how accurately you represent one genome, that’s not going to represent all of humanity. Now is a turning point: no longer genomics of the one standard human genome, but genomics for everybody.”

The researchers are making progress toward the goal of completing the full pangenome by 2024. The team is in the process of recruiting new individuals to represent some populations not included in the 1000 Genomes Project, particularly people of Middle Eastern and African ancestry. Miga, as the director of the Data Production Center at UCSC, will spearhead these efforts going forward.

In addition to completing the final pangenome reference, the researchers are working toward forming an international human pangenome project that would establish partnerships with researchers across the world. These partnerships would include a two-way skills and knowledge exchange, aimed to bring the skills and technology needed to create high-quality reference genomes into the hands of researchers worldwide so they can carry out their own research.

Other UCSC researchers on the main paper include Marina Haukness, Glenn Hickey, Julian Lucas, Jean Monlong, Xian Chang, Jordan Eizenga, Charles Markello, Adam Novak, Hugh Olsen, and Trevor Pesout.

Other institutions involved in the Human Pangenome Reference Consortium may be found on the project’s main page.

Funding for the HPRC was primarily provided by the National Human Genome Research Institute.
Share Button

Clearest snapshot of human genomic diversity

For more than 20 years, scientists have relied on the human reference genome, a consensus genetic sequence, as a standard against which to compare other genetic data. Used in countless studies, the reference genome has made it possible to identify genes implicated in specific diseases and trace the evolution of human traits, among other things.

But it has always been a flawed tool. One of its biggest problems is that about 70 percent of its data came from a single man of predominantly African-European background whose DNA was sequenced during the Human Genome Project, the first effort to capture all of a person’s DNA. As a result, it can tell us little about the 0.2 to one percent of genetic sequence that makes each of the seven billion people on this planet different from each other, creating an inherent bias in biomedical data believed to be responsible for some of the health disparities affecting patients today. Many genetic variants found in non-European populations, for instance, aren’t represented in the reference genome at all.

For years, researchers have called for a resource more inclusive of human diversity with which to diagnose diseases and guide medical treatments. Now scientists with the Human Pangenome Reference Consortium have made groundbreaking progress in characterizing the fraction of human DNA that varies between individuals. As they recently published in Nature, they’ve assembled genomic sequences of 47 people from around the world into a so-called pangenome in which more than 99 percent of each sequence is rendered with high accuracy.

Layered upon each other, these sequences revealed nearly 120 million DNA base pairs that were previously unseen.

While it’s still a work in progress, the pangenome is public and can be used by scientists around the world as a new standard human genome reference, says The Rockefeller University’s Erich D. Jarvis, one of the primary investigators.

“This complex genomic collection represents significantly more accurate human genetic diversity than has ever been captured before,” he says. “With a greater breadth and depth of genetic data at their disposal, and greater quality of genome assemblies, researchers can refine their understanding of the link between genes and disease traits, and accelerate clinical research.”

Sourcing diversity

Completed in 2003, the first draft of the human genome was relatively imprecise, but it became sharper over the years thanks to filled-in gaps, corrected errors, and advancing sequencing technology. Another milestone was reached last year, when the final eight percent of the genome — mainly tightly coiled DNA that doesn’t code for protein and repetitive DNA regions — was finally sequenced.

Despite this progress, the reference genome remained imperfect, especially with respect to the critical 0.2 to one percent of DNA representing diversity. The Human Pangenome Reference Consortium (HPRC), a government-funded collaboration between more than a dozen research institutions in the United States and Europe, was launched in 2019 to address this problem.

At the time, Jarvis, one of the consortium’s leaders, was honing advanced sequencing and computational methods through the Vertebrate Genomes Project, which aims to sequence all 70,000 vertebrate species. His and other collaborating labs decided to apply these advances for high-quality diploid genome assemblies to revealing the variation within a single vertebrate: Homo sapiens.

To collect a diversity of samples, the researchers turned to the 1000 Genomes Project, a public database of sequenced human genomes that includes more than 2500 individuals representing 26 geographically and ethnically varied populations. Most of the samples come from Africa, home to the planet’s largest human diversity.

“In many other large human genome diversity projects, the scientists selected mostly European samples,” Jarvis says. “We made a purposeful effort to do the opposite. We were trying to counteract the biases of the past.”

It’s likely that gene variants that could inform our knowledge of both common and rare diseases can be found among these populations.

Mom, dad, and child

But to broaden the gene pool, the researchers had to create crisper, clearer sequences of each individual-and the approaches developed by members of the Vertebrate Genome Project and associated consortiums were used to solve a longstanding technical problem in the field.

Every person inherits one genome from each parent, which is how we end up with two copies of every chromosome, giving us what’s known as a diploid genome. And when a person’s genome is sequenced, teasing apart parental DNA can be challenging. Older techniques and algorithms have routinely made errors when merging parental genetic data for an individual, resulting in a cloudy view. “The differences between mom’s and dad’s chromosomes are bigger than most people realize,” Jarvis says. “Mom may have 20 copies of a gene and dad only two.”

With so many genomes represented in a pangenome, that cloudiness threatened to develop into a thunderstorm of confusion. So the HPRC homed in a method developed by Adam Phillippy and Sergey Koren at the National Institutes of Health on parent-child “trios” — a mother, a father, and a child whose genomes had all been sequenced. Using the data from mom and dad, they were able to clear up the lines of inheritance and arrive at a higher-quality sequence for the child, which they then used for pangenome analysis.

New variations

The researchers’ analysis of 47 people yielded 94 distinct genome sequences, two for each set of chromosomes, plus the sex Y chromosome in males.

They then used advanced computational techniques to align and layer the 94 sequences. Of the 120 million DNA base pairs that were previously unseen or in a different location than they were noted to be in the previous reference, about 90 million derive from structural variations, which are differences in people’s DNA that arise when chunks of chromosomes are rearranged — moved, deleted, inverted, or with extra copies from duplications.

It’s an important discovery, Jarvis notes, because studies in recent years have established that structural variants play a major role in human health, as well as in population-specific diversity. “They can have dramatic effects on trait differences, disease, and gene function,” he says. “With so many new ones identified, there’s going to be a lot of new discoveries that weren’t possible before.”

Filling gaps

The pangenome assembly also fills in gaps that were due to repetitive sequences or duplicated genes. One example is the major histocompatibility complex (MHC), a cluster of genes that code proteins on the surface of cells that help the immune system recognize antigens, such as those from the SARS-CoV-2 virus.

“They’re really important, but it was impossible to study MHC diversity using the older sequencing methods,” Jarvis says. “We’re seeing much greater diversity than we expected. This new information will help us understand how immune responses against specific pathogens vary among people.” It could also lead to better methods to match organ transplant donors with and patients, or identify people at risk for developing autoimmune disease.

The team has also uncovered surprising new characteristics of centromeres, which lie at the cruxes of chromosomes and conduct cell division, pulling apart as cells duplicate. Mutations in centromeres can lead to cancers and other diseases.

Despite having highly repetitive DNA sequences, “centromeres are so diverse from one haplotype to another, that they can account for more than 50 percent of the genetic differences between people or maternal and paternal haplotypes even within one individual,” Jarvis says. “The centromeres seem to be one of the most rapidly evolving parts of the chromosome.”

Relationship building

The current 47-people pangenome is just a starting point, however. The HPRC’s ultimate goal is to produce high-quality, nearly error-free genomes from at least 350 individuals from diverse populations by mid-2024, a milestone that would make it possible to capture rare alleles that confer important adaptive traits. Tibetans, for example, have alleles related to oxygen use and UV light exposure that enable them to live at high altitudes.

A major challenge in collecting this data will be to gain trust from communities that have seen past abuses of biological data; for example, there are no samples in the current study from Native American nor Aboriginal peoples, who have been long been disregarded or exploited by scientific studies. But you don’t have to go far back in time to find examples of unethical use of genetic data: Just a few years ago, DNA samples from thousands of Africans in multiple countries were commercialized without the donors’ knowledge, consent, or benefit.

These offenses have sown mistrust against scientists among many populations. But by not being included, some of these groups could remain genetically obscure, leading to a perpetuation of the biases in the data — and to continued disparities in health outcomes.

“It’s a complex situation that’s going to require a lot of relationship building,” Jarvis says. “There’s greater sensitivity now.”

And even today, many groups are willing to participate. “There are individuals, institutions, and governmental bodies from different countries who are saying, ‘We want to be part of this. We want our population to be represented,'” Jarvis says. “We’re already making progress.”

Share Button

Researchers measure the light emitted by a sub-Neptune planet’s atmosphere

For more than a decade, astronomers have been trying to get a closer look at GJ 1214b, an exoplanet 40 light-years away from Earth. Their biggest obstacle is a thick layer of haze that blankets the planet, shielding it from the probing eyes of space telescopes and stymying efforts to study its atmosphere.

NASA’s new James Webb Space Telescope (JWST) solved that issue. The telescope’s infrared technology allows it to see planetary objects and features that were previously obscured by hazes, clouds or space dust, aiding astronomers in their search for habitable planets and early galaxies.

A team of researchers used JWST to observe GJ 1214b’s atmosphere by measuring the heat it emits while orbiting its host star. Their results, published in the journal Nature on May 10, 2023, represent the first time anyone has directly detected the light emitted by a sub-Neptune exoplanet — a category of planets that are larger than Earth but smaller than Neptune.

Though GJ 1214b is far too hot to be habitable, researchers discovered that its atmosphere likely contains water vapor — possibly even significant amounts — and is primarily composed of molecules heavier than hydrogen. University of Maryland Associate Professor of Astronomy Eliza Kempton, lead author of the Nature study, said their findings mark a turning point in the study of sub-Neptune planets like GJ 1214b.

“I’ve been on a quest to understand GJ 1214b for more than a decade,” Kempton said. “When we received the data for this Nature paper, we could see the light from the planet just disappear when it went behind its host star. That had never before been seen for this planet or for any other planet of its class, so JWST is really delivering on its promise.”

A ‘new light’

Sub-Neptunes are the most common type of planet in the Milky Way, though none exist in our solar system. Despite the murkiness of GJ 1214b’s atmosphere, Kempton and her co-authors determined the planet was still their best chance of observing a sub-Neptune’s atmosphere because of its bright but small host star.

In their Nature paper, the researchers measured the infrared light that GJ 1214b emitted over the course of about 40 hours — the time it takes the planet to orbit its star. As day turns to night, the amount of heat that shifts from one side of a planet to the other depends largely on what its atmosphere is made of. Known as a phase curve observation, this research method opened a new window into the planet’s atmosphere.

“JWST operates at longer wavelengths of light than previous observatories, which gives us access to the heat emitted by the planet and allows us to create a map of the planet’s temperature,” Kempton said. “We finally got to see GJ 1214b in a new light.”

By measuring the movement and fluctuation of heat, the researchers determined that GJ 1214b does not have an atmosphere dominated by hydrogen.

Potential water world?

The question of whether GJ 1214b contains water has long interested astronomers. Previous observations by NASA’s Hubble Space Telescope suggested that GJ 1214b could be a water world — a loose term for any planet that contains a significant amount of water.

The latest JWST data revealed traces of water, methane or some mix of the two. These substances match a subtle absorption of light seen in the wavelength range observed by JWST. Further studies will be needed to determine the exact makeup of the planet’s atmosphere, but Kempton said the evidence remains consistent with the possibility of large amounts of water.

“GJ 1214b, based on our observations, could be a water world,” Kempton said. “We think we detect water vapor, but it’s challenging because water vapor absorption overlaps with methane absorption, so we can’t say 100% that we detected water vapor and not methane. However, we see this evidence on both hemispheres of the planet, which heightens our confidence that there really is water there.”

Reflecting on the findings

The researchers made another surprising discovery in their study: GJ 1214b is incredibly reflective. The planet was not as hot as expected, which tells researchers that something in the atmosphere is reflecting light.

Kempton said there is plenty of room for follow-up studies, including ones that take a closer look at the high-altitude aerosols that form the haze — or possibly clouds — in GJ 1214b’s atmosphere. Previously, researchers thought it might be a dark, soot-like substance that absorbs light. However, the discovery that the exoplanet is reflective raises new questions.

“Whatever is making up the hazes or clouds is not what we expected. It’s bright, it’s reflective and that’s confusing and surprising,” Kempton said. “This is going to point us toward a lot of further studies to try to understand what those hazes could be.”

Share Button

Autistic teenager was stuck on general hospital ward for months

Experts say it was the wrong place for the 16-year-old, but she had nowhere else to go.

Share Button

Apprentice doctors considered in radical NHS plan

School leavers would be able to enrol to become doctors without having to pay to go to university.

Share Button

Poor diabetes care may be behind 7,000 excess deaths

More than half of people with diabetes missed out on vital checks last year, charity Diabetes UK says.

Share Button

Tory Minister’s Defence Of Coronation Policing Based On ‘Imaginary Things’

A government minister has been accused of relying on “imaginary things” while defending the heavily-criticised policing of the coronation.

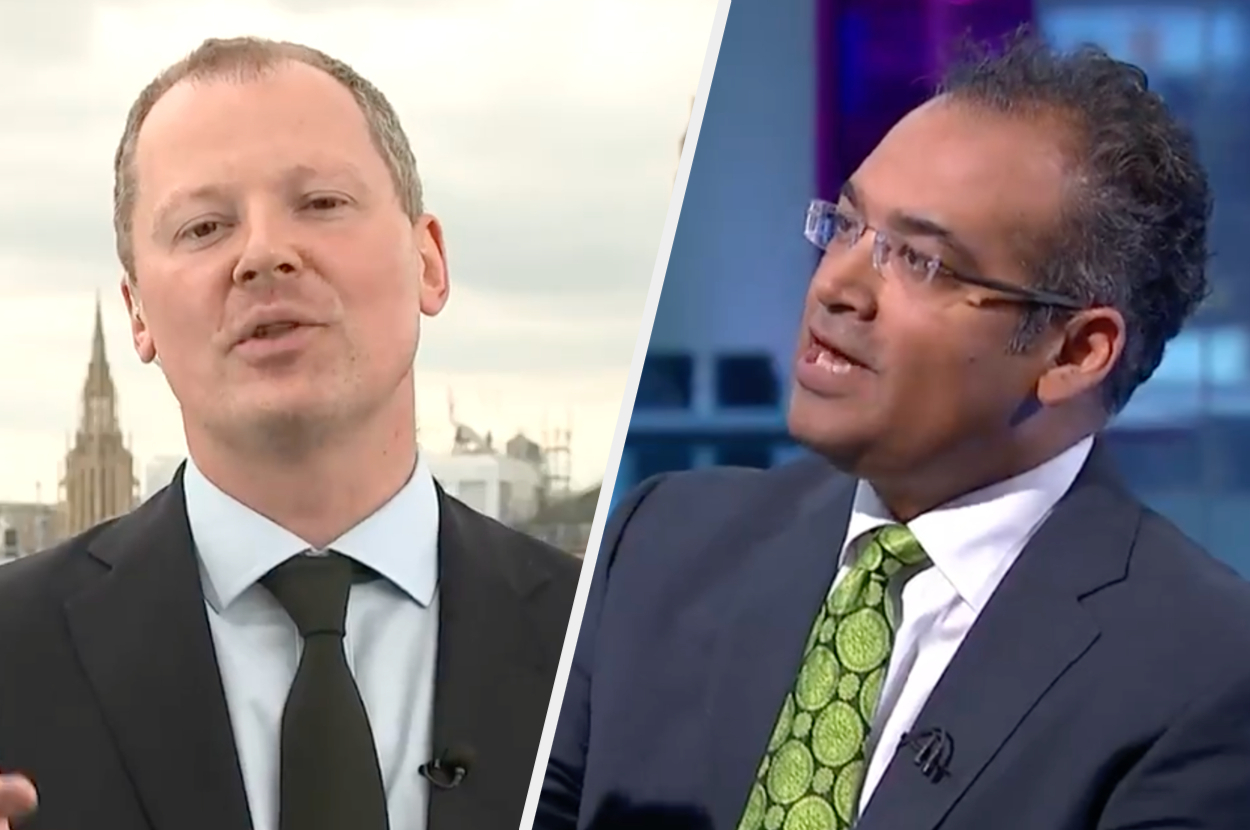
Neil O’Brien was questioned by Krishnan Guru-Murthy on Channel 4 News after an outcry over the arrest of anti-monarchy campaigners and women’s safety volunteers during the pageantry to mark King Charles officially ascending to the throne. All have been released without charge.

Facing a backlash over its heavy-handed approach, Metropolitan Police chief Mark Rowley has insisted police had “serious and reliable intelligence” that protesters planned to disrupt the coronation.

He said that suspects were found with bottles of white paint and that there was intelligence to suggest that some may use rape alarms or loud hailers during the coronation procession.

There were concerns among military personnel that loud noises could unsettle horses and cause multiple injuries, he said.

On Channel 4 News, O’Brien said: “On the one hand, obviously, sometimes the police get it wrong and there will be mistakes and it’s right that they apologise when that happens.

“On the other hand, they did bring off this fantastic national event, in a very smooth way and they were right, I think, to intervene where there are people who want to come and do dangerous things like setting off rape alarms, potentially deliberately startling horses and potentially all kinds of things could happen.”

Guru-Murthy tried to intervene by saying: “But they weren’t … you’re talking about imaginary things.”

O’Brien: “You say this an imaginary thing … if they had been allowed to cause all kinds of chaos, and there’d been all sorts of disruption …”

Guru-Murthy: “You’re imagining something that didn’t happen …”

O’Brien: “You’d then be saying the police should have intervened earlier.”

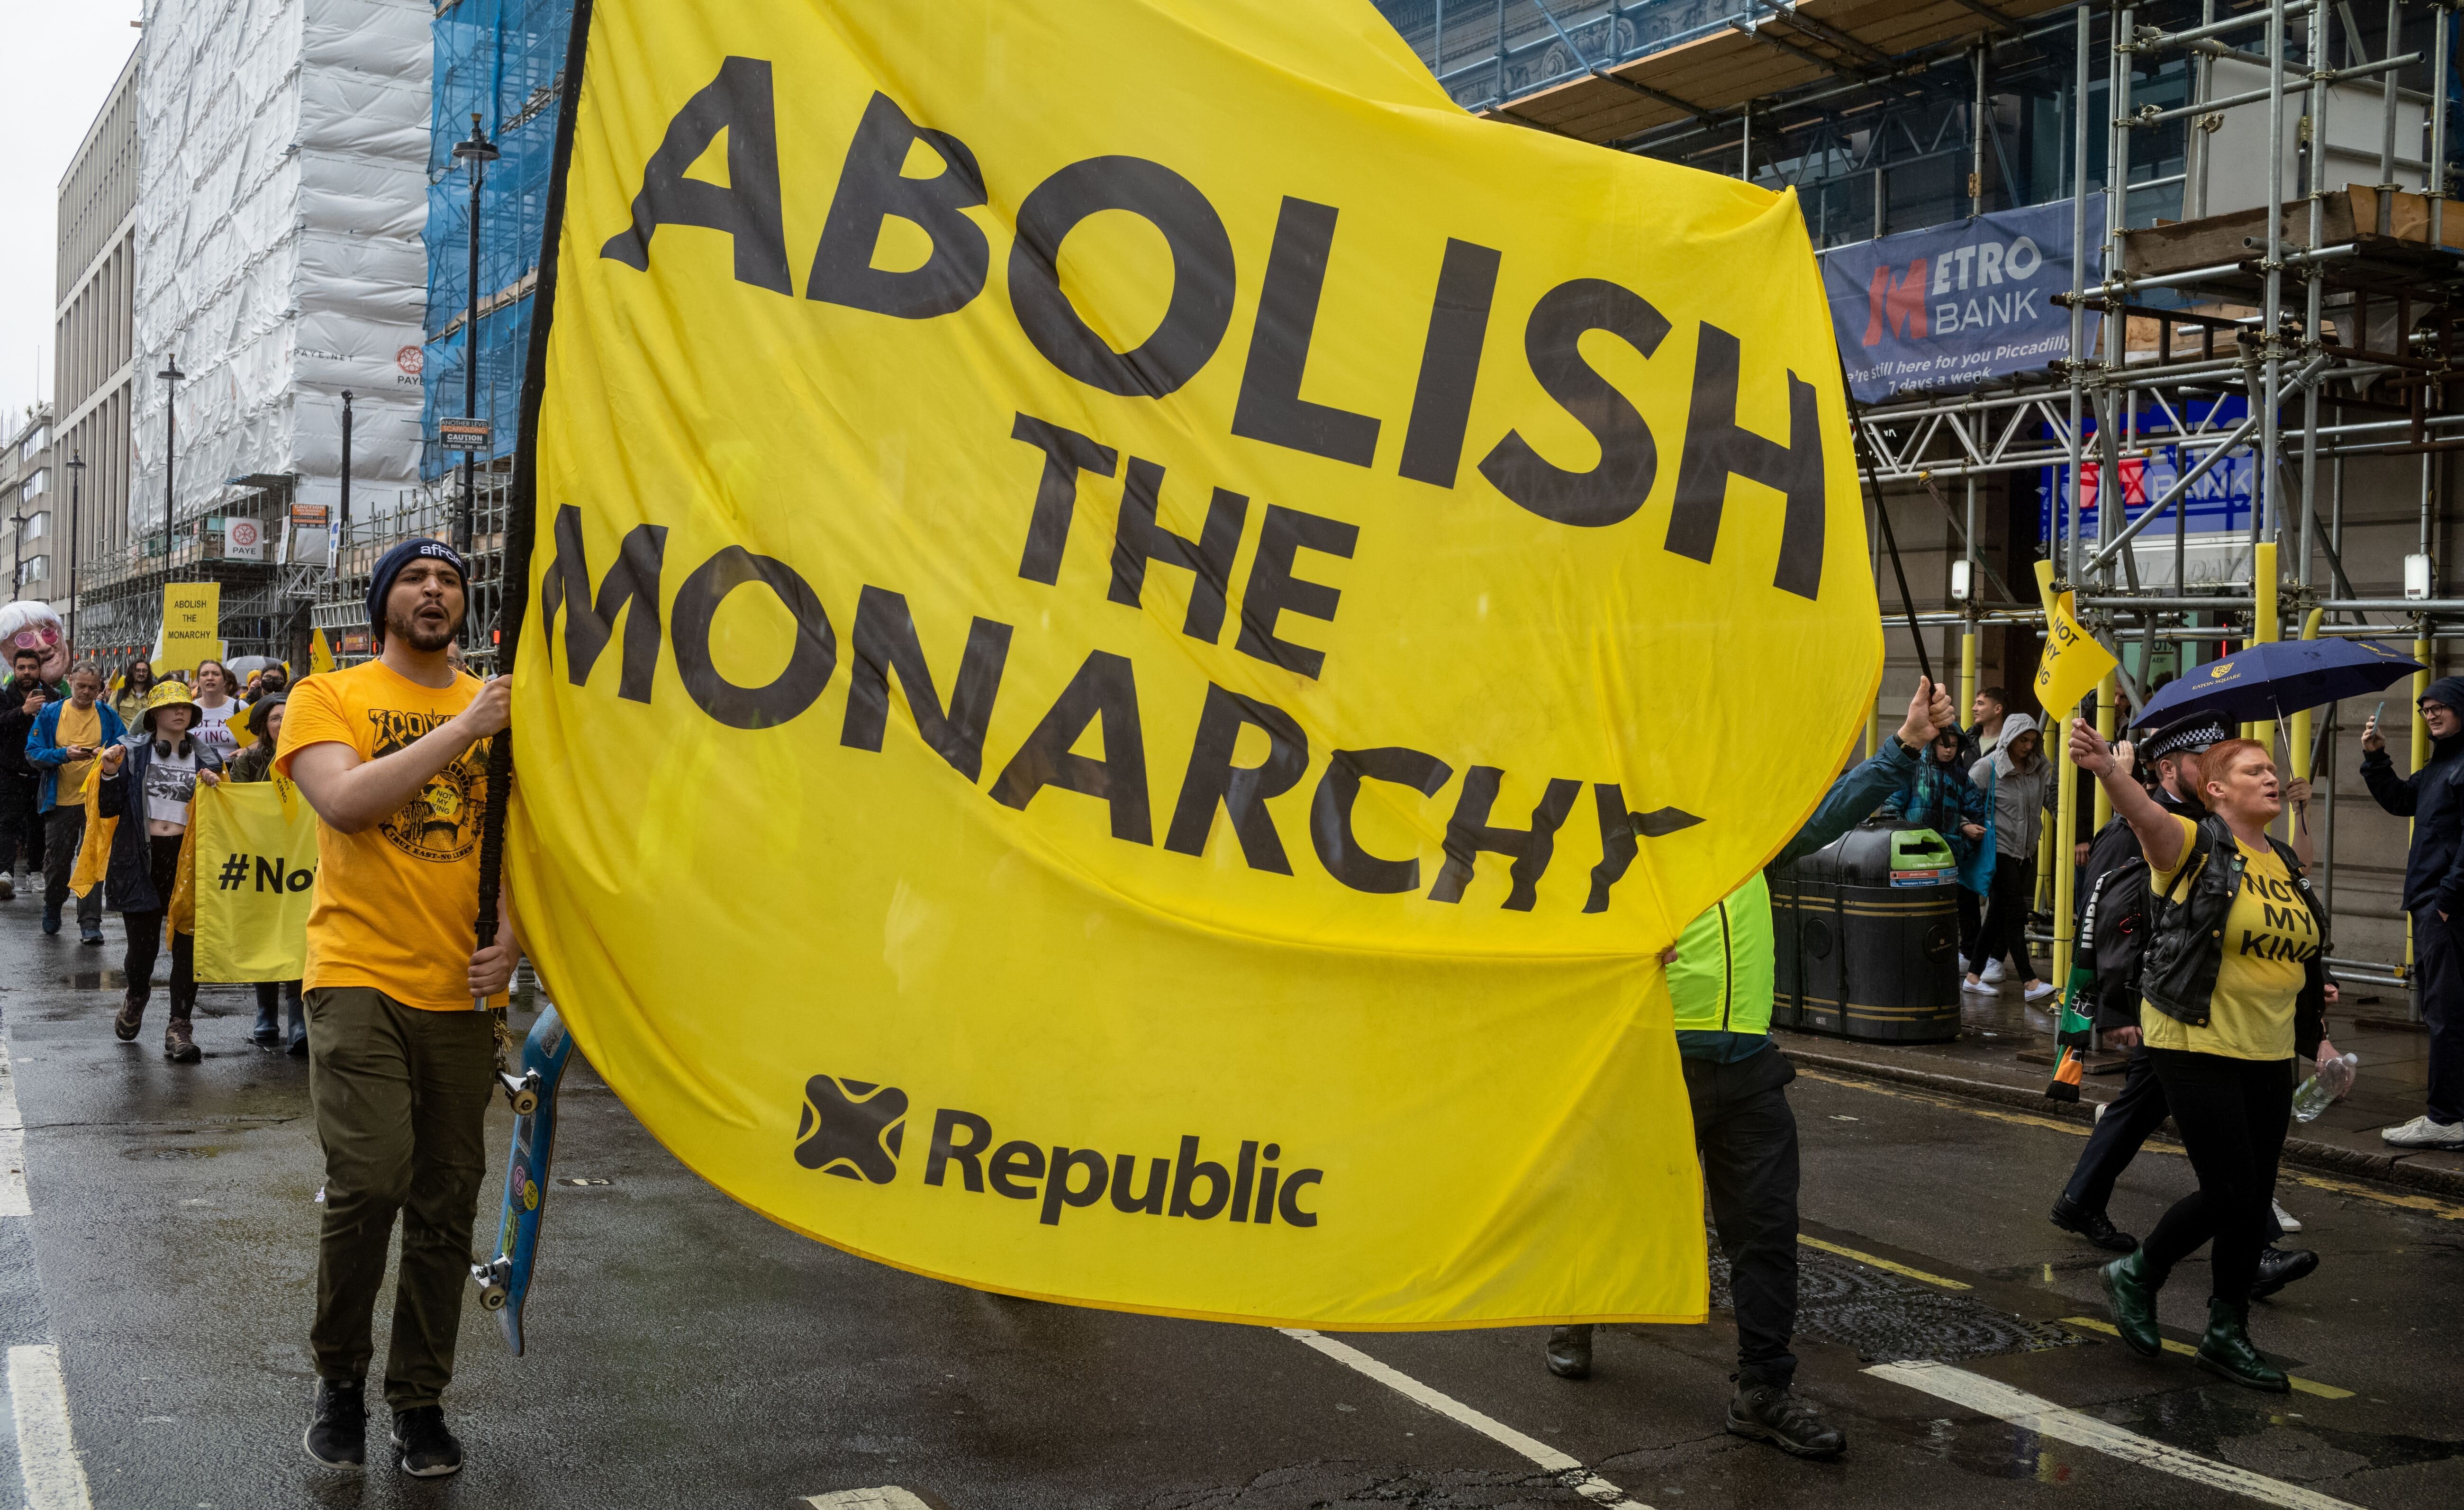
Six campaigners for the group Republic, which had liaised with the Met to organise a coronation day protest in Trafalgar Square, were arrested early on Saturday on suspicion of going equipped to lock-on. They were released 16 hours later.

Volunteers for charity Night Star, that hands out rape alarms to women on their way home from nights out, were arrested in the early hours of Saturday in Soho in central London.

In the Commons, Home Office minister Chris Philp, referred to “more than one plot to cause severe disruption by placing activated rape alarms in the path of horses to induce a stampede, and a separate plot to douse participants in the procession with paint”.

In total 64 people were arrested over the weekend, 52 over concerns that the coronation may be disrupted.

Share Button