Topological quantum simulation unlocks new potential in quantum computers

Researchers from the National University of Singapore (NUS) have successfully simulated higher-order topological (HOT) lattices with unprecedented accuracy using digital quantum computers. These complex lattice structures can help us understand advanced quantum materials with robust quantum states that are highly sought after in various technological applications.

The study of topological states of matter and their HOT counterparts has attracted considerable attention among physicists and engineers. This fervent interest stems from the discovery of topological insulators — materials that conduct electricity only on the surface or edges — while their interiors remain insulating. Due to the unique mathematical properties of topology, the electrons flowing along the edges are not hampered by any defects or deformations present in the material. Hence, devices made from such topological materials hold great potential for more robust transport or signal transmission technology.

Using many-body quantum interactions, a team of researchers led by Assistant Professor Lee Ching Hua from the Department of Physics under the NUS Faculty of Science has developed a scalable approach to encode large, high-dimensional HOT lattices representative of actual topological materials into the simple spin chains that exist in current-day digital quantum computers. Their approach leverages the exponential amounts of information that can be stored using quantum computer qubits while minimising quantum computing resource requirements in a noise-resistant manner. This breakthrough opens up a new direction in the simulation of advanced quantum materials using digital quantum computers, thereby unlocking new potential in topological material engineering.

The findings from this research have been published in the journal Nature Communications.

Asst Prof Lee said, “Existing breakthrough studies in quantum advantage are limited to highly-specific tailored problems. Finding new applications for which quantum computers provide unique advantages is the central motivation of our work.”

“Our approach allows us to explore the intricate signatures of topological materials on quantum computers with a level of precision that was previously unattainable, even for hypothetical materials existing in four dimensions” added Asst Prof Lee.

Despite the limitations of current noisy intermediate-scale quantum (NISQ) devices, the team is able to measure topological state dynamics and protected mid-gap spectra of higher-order topological lattices with unprecedented accuracy thanks to advanced in-house developed error mitigation techniques. This breakthrough demonstrates the potential of current quantum technology to explore new frontiers in material engineering. The ability to simulate high-dimensional HOT lattices opens new research directions in quantum materials and topological states, suggesting a potential route to achieving true quantum advantage in the future.

Share Button

What a submerged ancient bridge discovered in a Spanish cave reveals about early human settlement

A new study led by the University of South Florida has shed light on the human colonization of the western Mediterranean, revealing that humans settled there much earlier than previously believed. This research, detailed in a recent issue of the journal, Communications Earth & Environment, challenges long-held assumptions and narrows the gap between the settlement timelines of islands throughout the Mediterranean region.

Reconstructing early human colonization on Mediterranean islands is challenging due to limited archaeological evidence. By studying a 25-foot submerged bridge, an interdisciplinary research team — led by USF geology Professor Bogdan Onac — was able to provide compelling evidence of earlier human activity inside Genovesa Cave, located in the Spanish island of Mallorca.

“The presence of this submerged bridge and other artifacts indicates a sophisticated level of activity, implying that early settlers recognized the cave’s water resources and strategically built infrastructure to navigate it,” Onac said.

The cave, located near Mallorca’s coast, has passages now flooded due to rising sea levels, with distinct calcite encrustations forming during periods of high sea level. These formations, along with a light-colored band on the submerged bridge, serve as proxies for precisely tracking historical sea-level changes and dating the bridge’s construction.

Mallorca, despite being the sixth largest island in the Mediterranean, was among the last to be colonized. Previous research suggested human presence as far back as 9,000 years, but inconsistencies and poor preservation of the radiocarbon dated material, such as nearby bones and pottery, led to doubts about these findings. Newer studies have used charcoal, ash and bones found on the island to create a timeline of human settlement about 4,400 years ago. This aligns the timeline of human presence with significant environmental events, such as the extinction of the goat-antelope genus Myotragus balearicus.

By analyzing overgrowths of minerals on the bridge and the elevation of a coloration band on the bridge, Onac and the team discovered the bridge was constructed nearly 6,000 years ago, more than two-thousand years older than the previous estimation — narrowing the timeline gap between eastern and western Mediterranean settlements.

“This research underscores the importance of interdisciplinary collaboration in uncovering historical truths and advancing our understanding of human history,” Onac said.

This study was supported by several National Science Foundation grants and involved extensive fieldwork, including underwater exploration and precise dating techniques. Onac will continue exploring cave systems, some of which have deposits that formed millions of years ago, so he can identify preindustrial sea levels and examine the impact of modern greenhouse warming on sea-level rise.

This research was done in collaboration with Harvard University, the University of New Mexico and the University of Balearic Islands.

Share Button

Transparency is often lacking in datasets used to train large language models

In order to train more powerful large language models, researchers use vast dataset collections that blend diverse data from thousands of web sources.

But as these datasets are combined and recombined into multiple collections, important information about their origins and restrictions on how they can be used are often lost or confounded in the shuffle.

Not only does this raise legal and ethical concerns, it can also damage a model’s performance. For instance, if a dataset is miscategorized, someone training a machine-learning model for a certain task may end up unwittingly using data that are not designed for that task.

In addition, data from unknown sources could contain biases that cause a model to make unfair predictions when deployed.

To improve data transparency, a team of multidisciplinary researchers from MIT and elsewhere launched a systematic audit of more than 1,800 text datasets on popular hosting sites. They found that more than 70 percent of these datasets omitted some licensing information, while about 50 percent had information that contained errors.

Building off these insights, they developed a user-friendly tool called the Data Provenance Explorer that automatically generates easy-to-read summaries of a dataset’s creators, sources, licenses, and allowable uses.

“These types of tools can help regulators and practitioners make informed decisions about AI deployment, and further the responsible development of AI,” says Alex “Sandy” Pentland, an MIT professor, leader of the Human Dynamics Group in the MIT Media Lab, and co-author of a new open-access paper about the project.

The Data Provenance Explorer could help AI practitioners build more effective models by enabling them to select training datasets that fit their model’s intended purpose. In the long run, this could improve the accuracy of AI models in real-world situations, such as those used to evaluate loan applications or respond to customer queries.

“One of the best ways to understand the capabilities and limitations of an AI model is understanding what data it was trained on. When you have misattribution and confusion about where data came from, you have a serious transparency issue,” says Robert Mahari, a graduate student in the MIT Human Dynamics Group, a JD candidate at Harvard Law School, and co-lead author on the paper.

Mahari and Pentland are joined on the paper by co-lead author Shayne Longpre, a graduate student in the Media Lab; Sara Hooker, who leads the research lab Cohere for AI; as well as others at MIT, the University of California at Irvine, the University of Lille in France, the University of Colorado at Boulder, Olin College, Carnegie Mellon University, Contextual AI, ML Commons, and Tidelift. The research is published today in Nature Machine Intelligence.

Focus on finetuning

Researchers often use a technique called fine-tuning to improve the capabilities of a large language model that will be deployed for a specific task, like question-answering. For finetuning, they carefully build curated datasets designed to boost a model’s performance for this one task.

The MIT researchers focused on these fine-tuning datasets, which are often developed by researchers, academic organizations, or companies and licensed for specific uses.

When crowdsourced platforms aggregate such datasets into larger collections for practitioners to use for fine-tuning, some of that original license information is often left behind.

“These licenses ought to matter, and they should be enforceable,” Mahari says.

For instance, if the licensing terms of a dataset are wrong or missing, someone could spend a great deal of money and time developing a model they might be forced to take down later because some training data contained private information.

“People can end up training models where they don’t even understand the capabilities, concerns, or risk of those models, which ultimately stem from the data,” Longpre adds.

To begin this study, the researchers formally defined data provenance as the combination of a dataset’s sourcing, creating, and licensing heritage, as well as its characteristics. From there, they developed a structured auditing procedure to trace the data provenance of more than 1,800 text dataset collections from popular online repositories.

After finding that more than 70 percent of these datasets contained “unspecified” licenses that omitted much information, the researchers worked backward to fill in the blanks. Through their efforts, they reduced the number of datasets with “unspecified” licenses to around 30 percent.

Their work also revealed that the correct licenses were often more restrictive than those assigned by the repositories.

In addition, they found that nearly all dataset creators were concentrated in the global north, which could limit a model’s capabilities if it is trained for deployment in a different region. For instance, a Turkish language dataset created predominantly by people in the U.S. and China might not contain any culturally significant aspects, Mahari explains.

“We almost delude ourselves into thinking the datasets are more diverse than they actually are,” he says.

Interestingly, the researchers also saw a dramatic spike in restrictions placed on datasets created in 2023 and 2024, which might be driven by concerns from academics that their datasets could be used for unintended commercial purposes.

A user-friendly tool

To help others obtain this information without the need for a manual audit, the researchers built the Data Provenance Explorer. In addition to sorting and filtering datasets based on certain criteria, the tool allows users to download a data provenance card that provides a succinct, structured overview of dataset characteristics.

“We are hoping this is a step, not just to understand the landscape, but also help people going forward to make more informed choices about what data they are training on,” Mahari says.

In the future, the researchers want to expand their analysis to investigate data provenance for multimodal data, including video and speech. They also want to study how terms of service on websites that serve as data sources are echoed in datasets.

As they expand their research, they are also reaching out to regulators to discuss their findings and the unique copyright implications of fine-tuning data.

“We need data provenance and transparency from the outset, when people are creating and releasing these datasets, to make it easier for others to derive these insights,” Longpre says.
Share Button

Jess Phillips Says She Was Given Quicker NHS Treatment Because She Backed Gaza Ceasefire

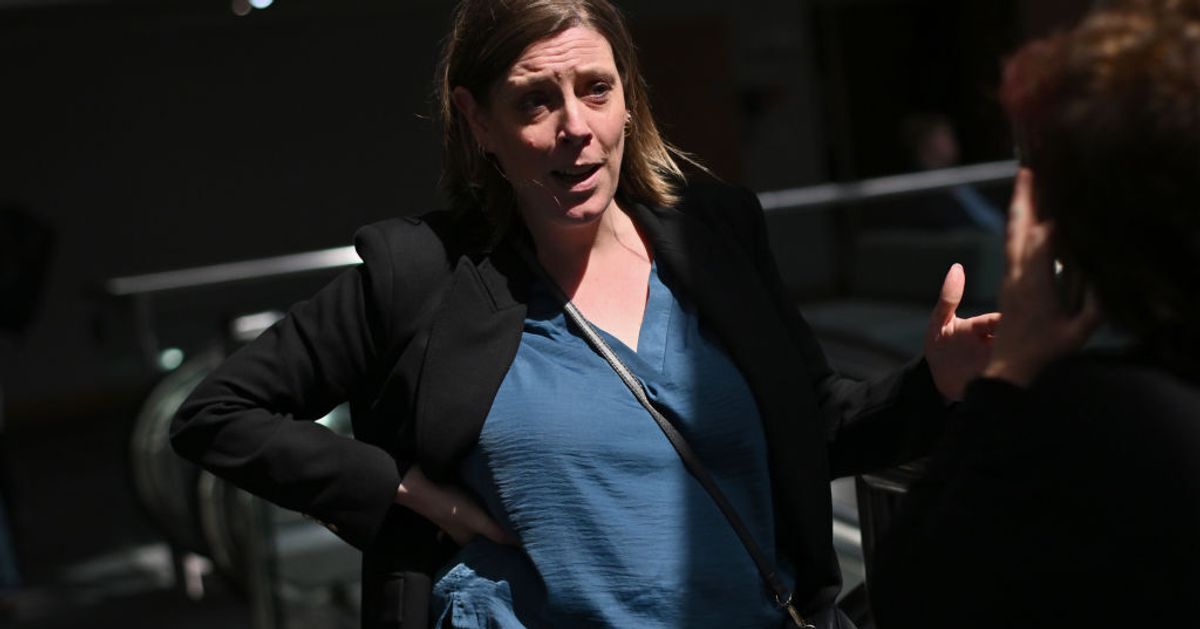
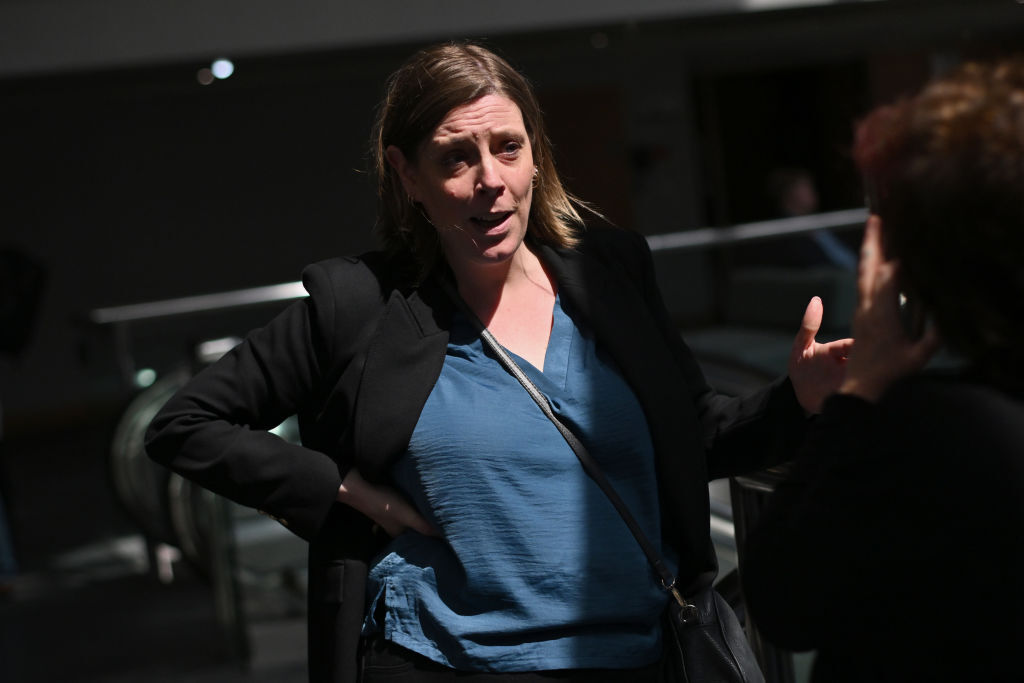
A government minister has claimed she got faster NHS treatment because she backed a ceasefire in Gaza.

According to the Daily Mail, Jess Phillips said she had gone to A&E at a hospital in her home city of Birmingham after suffering breathing difficulties.

Speaking at an ‘An Evening With Jess Phillips’ event at the Kiln Theatre in London, the Home Office minister said she had faced a lengthy wait due to overcrowding.

“I have genuinely seen better facilities, health facilities, in war zones, in developing countries around the world,” the MP told the audience.

She eventually made it to the front of the queue, but said that was “undoubtedly” thanks to her outspoken stance on the conflict between Israel and Hamas.

Phillips was one of eight Labour MPs who left the party’s frontbench last year after voting for a ceasefire.

The Birmingham Yardley MP said: “I got through because of who I am. Also the doctore who saw me was Palestinian, as it turns out. Almost all the doctors in Birmingham seemed to be.”

She added: “He was sort of like, ‘I like you. You voted for a ceasefire’. [Because of that] I got through quicker.”

HuffPost UK has contacted Phillips for a comment.

Earlier this month, the MP admitted she had made a “mistake” over a post she put on X during the recent riots.

Responding to footage showing a Sky News reporter being confronted by masked men in Birmingham, Phillips said it was caused by “misinformation” being spread in the area.

“These people came to this location because it has been spread that racists were coming to attack them,” she posted.

Following criticism of her remarks, Phillips said: “I think I almost certainly could have phrased it better.

“Anybody, regardless of who they are, whichever flag they wish to wave, anyone being a thug on our streets should not be tolerated.

“Of course I would choose my words more carefully. I’m more than happy to say that when I make a mistake, absolutely.”

Share Button

What is the plan to give polio vaccines to children in Gaza?

Pauses to fighting will allow hundreds of thousands of Gaza children to be vaccinated against polio.

Share Button

Hospices funding woes bring cuts in beds and jobs

Five hospices caring for terminally ill people say they must cut staff because of financial pressures.

Share Button

Here’s How Many Seconds Science Says It Takes To Poop, And Wow, Am I Doing It Wrong

We’ve already shared at HuffPost that you’re not actually meant to sit on the loo for more than five minutes at a time.

We’ve also written about the fact that, although women tend to have more complications with their BMs, men spend a lot more time on the porcelain throne.

While writing the second article, though, I learned something that turned my world inside out.

According to some scientists, most mammals (and yep, we’re a part of that) should take no longer than 12 of Gillian McKeith’s own seconds to pass a poop.

What? Why?

Well, okay, it’s not as exact as that.

But according to a paper published by the Royal Society of Chemistry in their journal Soft Matter (I know), most mammals take between five and 19 seconds; 12 seconds on average.

The study, called Hydrodynamics of Defecation, looked at a range of mammals of different sizes at Zoo Atlanta. They didn’t study humans.

It found that, from a cat to an elephant, a majority (roughly 66%) of mammals took the same, sub-20 amount of seconds to pass a stool.

Patricia Yang, a mechanical engineer at the Georgia Institute of Technology in Atlanta, said that that may be because “The smell of body waste attracts predators, which is dangerous for animals.”

“If they stay longer doing their thing, they’re exposing themselves and risking being discovered,” the study’s main author told New Scientist.

How come it all takes the same time?

Pooping doesn’t work the way most of us think, the study revealed.

We’re not pushing the BMs out like removing toothpaste from a tube; “It’s more like a plug that just goes through a chute,” the study’s lead author said.

That’s partly because of the mucus that lines our gut and makes it slippery.

Add to that the fact that poop seems to take up a similar amount of space in the gut before it’s excreted across most species (five times the diameter of the mammals’ rectum), and it’s no wonder they exert a similar amount of pressure and take around the same time.

Though, again, the study didn’t look at humans, its lead author said “If it’s taking far longer than 12 seconds, I’d say you should go see someone about it.”

“But you can’t count the newspaper time,” she added.

Share Button

‘Bionic’ peer calls for better care for amputees

Lord Mackinlay says prosthetics currently on offer could leave people “feeling in a pit of despair”.

Share Button

Plan for workplace health checks to curb heart disease

The government hopes the new scheme will save lives and help ease the pressure on the NHS.

Share Button

Restrained and scared – the £100k schools failing vulnerable children

A pupil who says she was repeatedly restrained took her independent special school to court.

Share Button